GenAI London 2026 Speakers
GenAI London 2026 Speakers
GenAI London 2026 Speakers
Speakers
Hear big ideas
from thought leaders

Applied AI Architect
From AI Users to AI Builders: Turning Ideas into Working Tools
AI is expanding who can build software. People who understand a business problem can increasingly turn an idea into a working tool, changing how expertise becomes useful solutions. What does this mean for teams, their skills and the work they choose to do?
In this 10-minute talk, Stephanie Anani follows one illustrative workflow from a recurring business problem to an AI-assisted prototype and a decision about whether it is ready to share. The example explores what domain experts can now do themselves, where engineers and other specialists remain essential, and how to preserve learning and ownership as building becomes easier.
Attendees will leave with three takeaways: how to recognise a small, worthwhile problem to build for; how to distinguish a promising prototype from a tool colleagues can depend on; and how broader building capability can strengthen collaboration and human agency.
From GenAI Tools to GenAI-Native Organisations
Applied AI Architect
From AI Users to AI Builders: Turning Ideas into Working Tools
AI is expanding who can build software. People who understand a business problem can increasingly turn an idea into a working tool, changing how expertise becomes useful solutions. What does this mean for teams, their skills and the work they choose to do?
In this 10-minute talk, Stephanie Anani follows one illustrative workflow from a recurring business problem to an AI-assisted prototype and a decision about whether it is ready to share. The example explores what domain experts can now do themselves, where engineers and other specialists remain essential, and how to preserve learning and ownership as building becomes easier.
Attendees will leave with three takeaways: how to recognise a small, worthwhile problem to build for; how to distinguish a promising prototype from a tool colleagues can depend on; and how broader building capability can strengthen collaboration and human agency.
From GenAI Tools to GenAI-Native Organisations

Principal Product Manager
Answers You Can Trust: Engineering Reliable AI Systems That Earn It
Anyone can build an AI system that produces plausible answers. Building one people can actually trust is a different engineering discipline. Drawing on lessons from building answer systems at scale, this talk covers the full trust stack.
First, engineering context and orchestrating heterogeneous tools (search, MCP integrations, internal data sources) so answers are grounded in evidence rather than hallucinated. Second, measuring what matters, using groundedness, faithfulness, and tool correctness instead of vanity benchmarks. Third, closing the loop with automated evals, LLM-as-judge scoring, and production feedback pipelines that let the system evaluate itself and propose its own improvements.
Attendees will leave with a practical framework for turning an AI assistant from a confident guesser into a dependable instrument whose answers earn their trust.
Principal Product Manager
Answers You Can Trust: Engineering Reliable AI Systems That Earn It
Anyone can build an AI system that produces plausible answers. Building one people can actually trust is a different engineering discipline. Drawing on lessons from building answer systems at scale, this talk covers the full trust stack.
First, engineering context and orchestrating heterogeneous tools (search, MCP integrations, internal data sources) so answers are grounded in evidence rather than hallucinated. Second, measuring what matters, using groundedness, faithfulness, and tool correctness instead of vanity benchmarks. Third, closing the loop with automated evals, LLM-as-judge scoring, and production feedback pipelines that let the system evaluate itself and propose its own improvements.
Attendees will leave with a practical framework for turning an AI assistant from a confident guesser into a dependable instrument whose answers earn their trust.

Solutions Architect Lead, EMEA
Build a Privacy-Safe GenAI App in 45 Minutes with Skyflow Detect
Generative AI applications are increasingly processing sensitive customer information, often sending personal data to LLMs without adequate protection. How can developers build useful AI applications while minimizing exposure of personally identifiable information (PII)?
In this hands-on workshop, participants will build a privacy-aware AI assistant for a fictional insurance company using Python, Google Colab, Skyflow Detect, and Claude.
Starting with realistic customer claims containing names, email addresses, phone numbers, and other sensitive information, participants will learn how to automatically detect and de-identify PII before it reaches an LLM.
We'll explore how Skyflow Detect identifies sensitive entities, replaces them with vault-backed tokens, and preserves the context needed for meaningful AI responses. Participants will then integrate a real LLM to summarize insurance claims using protected data and explore how authorized applications can selectively re-identify information when needed.
By the end of the workshop, participants will understand how to:
Detect sensitive information in unstructured text.
Apply de-identification and tokenization before sending data to LLMs.
Build an end-to-end privacy-aware GenAI workflow.
Understand the role of secure vaults and controlled re-identification.
Participants will leave with a working Google Colab notebook and a practical architecture they can adapt to their own AI applications.
Participation is subject to approval by the workshop organiser, so please apply to secure your place.
Solutions Architect Lead, EMEA
Build a Privacy-Safe GenAI App in 45 Minutes with Skyflow Detect
Generative AI applications are increasingly processing sensitive customer information, often sending personal data to LLMs without adequate protection. How can developers build useful AI applications while minimizing exposure of personally identifiable information (PII)?
In this hands-on workshop, participants will build a privacy-aware AI assistant for a fictional insurance company using Python, Google Colab, Skyflow Detect, and Claude.
Starting with realistic customer claims containing names, email addresses, phone numbers, and other sensitive information, participants will learn how to automatically detect and de-identify PII before it reaches an LLM.
We'll explore how Skyflow Detect identifies sensitive entities, replaces them with vault-backed tokens, and preserves the context needed for meaningful AI responses. Participants will then integrate a real LLM to summarize insurance claims using protected data and explore how authorized applications can selectively re-identify information when needed.
By the end of the workshop, participants will understand how to:
Detect sensitive information in unstructured text.
Apply de-identification and tokenization before sending data to LLMs.
Build an end-to-end privacy-aware GenAI workflow.
Understand the role of secure vaults and controlled re-identification.
Participants will leave with a working Google Colab notebook and a practical architecture they can adapt to their own AI applications.
Participation is subject to approval by the workshop organiser, so please apply to secure your place.

Sr. Staff Sales Engineer
The Database Estate Nobody Provisioned
AI agents are beginning to create and remove databases programmatically, while many teams still rely on processes built for people to provision and manage them. As agent traffic grows, some infrastructure will absorb the demand; other teams may face rising costs and operational sprawl.
This session explores what it takes to manage one database estate across workloads created by both people and agents, and asks a practical question: what does your database estate cost today, and what might it cost at ten times the agent traffic?
Build Fast, Don’t Drown: Running the Database Behind Your AI Agents
As AI agents create and use more workloads, the databases behind them can quickly become harder to manage. This hands-on workshop explores how to keep pace without adding operational sprawl or requiring a DBA for every database.
We’ll start with a live demo, spinning up a workload the way an agent might and showing a virtual cluster go live in seconds without a provisioning ticket. From there, we’ll look at what happens as workloads multiply: ownership becomes less clear, capacity goes unused, and costs become fragmented. We’ll explore how consolidation and consumption-based pricing can help teams manage that growth.
The workshop will then introduce Aegis, demonstrating how an agentic operations layer can observe the database estate and recommend actions, while maintaining human oversight and governance. We’ll conclude with an open discussion about the state of attendees’ database estates today and how they expect them to change as AI agent workloads grow.
Participation is subject to approval by the workshop organiser, so please apply to secure your place.
Sr. Staff Sales Engineer
The Database Estate Nobody Provisioned
AI agents are beginning to create and remove databases programmatically, while many teams still rely on processes built for people to provision and manage them. As agent traffic grows, some infrastructure will absorb the demand; other teams may face rising costs and operational sprawl.
This session explores what it takes to manage one database estate across workloads created by both people and agents, and asks a practical question: what does your database estate cost today, and what might it cost at ten times the agent traffic?
Build Fast, Don’t Drown: Running the Database Behind Your AI Agents
As AI agents create and use more workloads, the databases behind them can quickly become harder to manage. This hands-on workshop explores how to keep pace without adding operational sprawl or requiring a DBA for every database.
We’ll start with a live demo, spinning up a workload the way an agent might and showing a virtual cluster go live in seconds without a provisioning ticket. From there, we’ll look at what happens as workloads multiply: ownership becomes less clear, capacity goes unused, and costs become fragmented. We’ll explore how consolidation and consumption-based pricing can help teams manage that growth.
The workshop will then introduce Aegis, demonstrating how an agentic operations layer can observe the database estate and recommend actions, while maintaining human oversight and governance. We’ll conclude with an open discussion about the state of attendees’ database estates today and how they expect them to change as AI agent workloads grow.
Participation is subject to approval by the workshop organiser, so please apply to secure your place.

Staff Software Engineer
Trying Again vs. Getting Better: How AI Agents Improve
When an AI agent succeeds on its fifth attempt, has it learned anything—or simply tried enough times? Through an accessible demonstration, Royston will compare repeated attempts, feedback-driven refinement, and carrying lessons into new tasks. We’ll explore what changes between these approaches, when apparent progress fails to transfer, and how human choices about goals and constraints shape the outcome.
Staff Software Engineer
Trying Again vs. Getting Better: How AI Agents Improve
When an AI agent succeeds on its fifth attempt, has it learned anything—or simply tried enough times? Through an accessible demonstration, Royston will compare repeated attempts, feedback-driven refinement, and carrying lessons into new tasks. We’ll explore what changes between these approaches, when apparent progress fails to transfer, and how human choices about goals and constraints shape the outcome.

CEO and Founder
What Makes AI Deployment Work vs. Not
Everyone is building with AI, but few are deploying it successfully. Join Husayn Kassai, Founder & CEO of Ollo, for a practical look at why so many AI initiatives stall: unclear decision-making, weak ownership, and bots bolted onto workflows that are already full of friction.
Husayn introduces the AI "harness": the organisational layer of judgment, governance, context and tooling that turns what models can do into real business impact. You'll learn how to define what good looks like, who should own AI-assisted decisions, and how to give systems the access and context they need.
Attendees will leave with a framework for choosing between generalist tools, specialist products and custom workflows. They'll also see why the ability to deploy AI must be built in-house. Successful AI isn't model-led; it's organisation-led.
Can Europe Lead the Future of GenAI?
CEO and Founder
What Makes AI Deployment Work vs. Not
Everyone is building with AI, but few are deploying it successfully. Join Husayn Kassai, Founder & CEO of Ollo, for a practical look at why so many AI initiatives stall: unclear decision-making, weak ownership, and bots bolted onto workflows that are already full of friction.
Husayn introduces the AI "harness": the organisational layer of judgment, governance, context and tooling that turns what models can do into real business impact. You'll learn how to define what good looks like, who should own AI-assisted decisions, and how to give systems the access and context they need.
Attendees will leave with a framework for choosing between generalist tools, specialist products and custom workflows. They'll also see why the ability to deploy AI must be built in-house. Successful AI isn't model-led; it's organisation-led.
Can Europe Lead the Future of GenAI?

Chief Marketing Strategy & Operations Officer
Marketing Transformation: People, platforms and perseverance.
Mark Dewings (CEO, Ogilvy Consulting UK) will host Kate Mackie (Chief Marketing Strategy & Operations Officer, EY), Özgür Kirazci (Senior Marketing Director, EMEA Platforms and Devices, Google) and Dr Laura Weiss (WPP, Human-AI Strategy & Workforce Planning Lead) to hear their views on AI-enabled marketing transformation. The discussion will cover what has actually changed, how organisations should transform, views on the future marketing organisation, and more.
Chief Marketing Strategy & Operations Officer
Marketing Transformation: People, platforms and perseverance.
Mark Dewings (CEO, Ogilvy Consulting UK) will host Kate Mackie (Chief Marketing Strategy & Operations Officer, EY), Özgür Kirazci (Senior Marketing Director, EMEA Platforms and Devices, Google) and Dr Laura Weiss (WPP, Human-AI Strategy & Workforce Planning Lead) to hear their views on AI-enabled marketing transformation. The discussion will cover what has actually changed, how organisations should transform, views on the future marketing organisation, and more.

Technical Senior
Evaluation of LLMs and Building Responsible AI Systems
In this session, I will discuss how different responsible AI techniques can be leveraged to evaluate the performance, reliability, and limitations of Large Language Models (LLMs). By systematically varying prompts, we uncover model behavior across various tasks, including reasoning, summarization, and code generation. We’ll discuss benchmarking methods, prompt sensitivity, and how to design effective evaluation frameworks.
Technical Senior
Evaluation of LLMs and Building Responsible AI Systems
In this session, I will discuss how different responsible AI techniques can be leveraged to evaluate the performance, reliability, and limitations of Large Language Models (LLMs). By systematically varying prompts, we uncover model behavior across various tasks, including reasoning, summarization, and code generation. We’ll discuss benchmarking methods, prompt sensitivity, and how to design effective evaluation frameworks.
Engineering Manager
Institutional Memory: Turning AI Coding Assistants into a Team's Collective Brain
Every engineer using Claude Code or Copilot generates a session full of hard-won context: gotchas, conventions, decisions. Today, that knowledge evaporates the moment the session ends, and the next engineer rediscovers it the hard way.
This talk shares an early but promising system for capturing that context and turning it into shared team memory. Sessions are logged centrally, then processed into durable, tagged knowledge fed back into future sessions.
Filipe will cover what's working, what's still limited, and the harder problems ahead: keeping extracted knowledge accurate rather than confidently wrong, who owns retiring stale entries, and stopping shared memory becoming another thing to maintain. A practitioner's account from an engineering manager building this now, not a finished product pitch.
Key takeaways
A working pattern for capturing team knowledge from AI coding sessions
Why "most frequent" metrics hide the moments that matter most
The real bottleneck: extraction quality, not storage
More about Filipe: https://alpomar.dev
Engineering Manager
Institutional Memory: Turning AI Coding Assistants into a Team's Collective Brain
Every engineer using Claude Code or Copilot generates a session full of hard-won context: gotchas, conventions, decisions. Today, that knowledge evaporates the moment the session ends, and the next engineer rediscovers it the hard way.
This talk shares an early but promising system for capturing that context and turning it into shared team memory. Sessions are logged centrally, then processed into durable, tagged knowledge fed back into future sessions.
Filipe will cover what's working, what's still limited, and the harder problems ahead: keeping extracted knowledge accurate rather than confidently wrong, who owns retiring stale entries, and stopping shared memory becoming another thing to maintain. A practitioner's account from an engineering manager building this now, not a finished product pitch.
Key takeaways
A working pattern for capturing team knowledge from AI coding sessions
Why "most frequent" metrics hide the moments that matter most
The real bottleneck: extraction quality, not storage
More about Filipe: https://alpomar.dev

Sr Marketing Director, EMEA Platforms & Devices; UKI Devices & Services
Marketing Transformation: People, platforms and perseverance.
Mark Dewings (CEO, Ogilvy Consulting UK) will host Kate Mackie (Chief Marketing Strategy & Operations Officer, EY), Özgür Kirazci (Senior Marketing Director, EMEA Platforms and Devices, Google) and Dr Laura Weiss (WPP, Human-AI Strategy & Workforce Planning Lead) to hear their views on AI-enabled marketing transformation. The discussion will cover what has actually changed, how organisations should transform, views on the future marketing organisation, and more.
Sr Marketing Director, EMEA Platforms & Devices; UKI Devices & Services
Marketing Transformation: People, platforms and perseverance.
Mark Dewings (CEO, Ogilvy Consulting UK) will host Kate Mackie (Chief Marketing Strategy & Operations Officer, EY), Özgür Kirazci (Senior Marketing Director, EMEA Platforms and Devices, Google) and Dr Laura Weiss (WPP, Human-AI Strategy & Workforce Planning Lead) to hear their views on AI-enabled marketing transformation. The discussion will cover what has actually changed, how organisations should transform, views on the future marketing organisation, and more.

Director of Engineering, Intelligence Systems
AI Evals at 80M Users a Month: Scaling Expert Judgement with LLM Judges
Evaluating the customer-facing AI for a women's health app used by 80 million people a month means no team of experts can read every answer. So LLM judges do the reading, and that only works if the judges decide the way the experts would. Out of the box, they often don't: a judge with a sensible rubric can agree with experts barely better than chance.
Health adds a second problem. A judge that is too strict blocks answers people need, and one that is too lenient lets unsafe ones through. Flo and Mentiora split the work in two. Medical judges, built with clinicians, decide whether an answer is safe. Usefulness judges, built with product experts, decide whether it actually helps. The two pull in opposite directions. When we tuned a model to pass the medical judges, it got safer, but less useful. Together the judges form the foundation for a quality loop that raises the customer experience.
In this talk we show how we got from a small sample of expert labels to judges that hold up against those experts. We cover how to measure a judge's agreement with experts before you trust it, and how to search across judge and aggregation combinations instead of hand-tuning one prompt. We show how to combine several narrow judges into one release verdict with hard gates, and why safety and usefulness need separate verdicts rather than one blended score. We finish with where humans still have to stay in the loop.
Director of Engineering, Intelligence Systems
AI Evals at 80M Users a Month: Scaling Expert Judgement with LLM Judges
Evaluating the customer-facing AI for a women's health app used by 80 million people a month means no team of experts can read every answer. So LLM judges do the reading, and that only works if the judges decide the way the experts would. Out of the box, they often don't: a judge with a sensible rubric can agree with experts barely better than chance.
Health adds a second problem. A judge that is too strict blocks answers people need, and one that is too lenient lets unsafe ones through. Flo and Mentiora split the work in two. Medical judges, built with clinicians, decide whether an answer is safe. Usefulness judges, built with product experts, decide whether it actually helps. The two pull in opposite directions. When we tuned a model to pass the medical judges, it got safer, but less useful. Together the judges form the foundation for a quality loop that raises the customer experience.
In this talk we show how we got from a small sample of expert labels to judges that hold up against those experts. We cover how to measure a judge's agreement with experts before you trust it, and how to search across judge and aggregation combinations instead of hand-tuning one prompt. We show how to combine several narrow judges into one release verdict with hard gates, and why safety and usefulness need separate verdicts rather than one blended score. We finish with where humans still have to stay in the loop.

Global Head of Human–AI Strategy & Innovation
Marketing Transformation: People, platforms and perseverance.
Mark Dewings (CEO, Ogilvy Consulting UK) will host Kate Mackie (Chief Marketing Strategy & Operations Officer, EY), Özgür Kirazci (Senior Marketing Director, EMEA Platforms and Devices, Google) and Dr Laura Weiss (WPP, Human-AI Strategy & Workforce Planning Lead) to hear their views on AI-enabled marketing transformation. The discussion will cover what has actually changed, how organisations should transform, views on the future marketing organisation, and more.
Global Head of Human–AI Strategy & Innovation
Marketing Transformation: People, platforms and perseverance.
Mark Dewings (CEO, Ogilvy Consulting UK) will host Kate Mackie (Chief Marketing Strategy & Operations Officer, EY), Özgür Kirazci (Senior Marketing Director, EMEA Platforms and Devices, Google) and Dr Laura Weiss (WPP, Human-AI Strategy & Workforce Planning Lead) to hear their views on AI-enabled marketing transformation. The discussion will cover what has actually changed, how organisations should transform, views on the future marketing organisation, and more.

CEO & Founder
AI Evals at 80M Users a Month: Scaling Expert Judgement with LLM Judges
Evaluating the customer-facing AI for a women's health app used by 80 million people a month means no team of experts can read every answer. So LLM judges do the reading, and that only works if the judges decide the way the experts would. Out of the box, they often don't: a judge with a sensible rubric can agree with experts barely better than chance.
Health adds a second problem. A judge that is too strict blocks answers people need, and one that is too lenient lets unsafe ones through. Flo and Mentiora split the work in two. Medical judges, built with clinicians, decide whether an answer is safe. Usefulness judges, built with product experts, decide whether it actually helps. The two pull in opposite directions. When we tuned a model to pass the medical judges, it got safer, but less useful. Together the judges form the foundation for a quality loop that raises the customer experience.
In this talk we show how we got from a small sample of expert labels to judges that hold up against those experts. We cover how to measure a judge's agreement with experts before you trust it, and how to search across judge and aggregation combinations instead of hand-tuning one prompt. We show how to combine several narrow judges into one release verdict with hard gates, and why safety and usefulness need separate verdicts rather than one blended score. We finish with where humans still have to stay in the loop.
Can Europe Lead the Future of GenAI?
CEO & Founder
AI Evals at 80M Users a Month: Scaling Expert Judgement with LLM Judges
Evaluating the customer-facing AI for a women's health app used by 80 million people a month means no team of experts can read every answer. So LLM judges do the reading, and that only works if the judges decide the way the experts would. Out of the box, they often don't: a judge with a sensible rubric can agree with experts barely better than chance.
Health adds a second problem. A judge that is too strict blocks answers people need, and one that is too lenient lets unsafe ones through. Flo and Mentiora split the work in two. Medical judges, built with clinicians, decide whether an answer is safe. Usefulness judges, built with product experts, decide whether it actually helps. The two pull in opposite directions. When we tuned a model to pass the medical judges, it got safer, but less useful. Together the judges form the foundation for a quality loop that raises the customer experience.
In this talk we show how we got from a small sample of expert labels to judges that hold up against those experts. We cover how to measure a judge's agreement with experts before you trust it, and how to search across judge and aggregation combinations instead of hand-tuning one prompt. We show how to combine several narrow judges into one release verdict with hard gates, and why safety and usefulness need separate verdicts rather than one blended score. We finish with where humans still have to stay in the loop.
Can Europe Lead the Future of GenAI?

Founder & Managing Director
Proving the Decision: What Agentic AI Requires of Human Judgement Now
Agentic AI moves the human decision earlier and compresses the time to make it, raising the bar for what counts as judgement rather than reflex. The question now is whether the person still in the loop can see clearly, hold their position under speed and pressure, and exercise authority they can prove. This session sets out what agentic AI requires of human judgement now: decisions tested under time compression, evidenced when they matter, and owned by a named person who can show they held. Humans still decide. The proof required to show that judgement holds is what has changed. Key takeaways:
Judgement counts as authority only when it has been tested under real pressure and time compression.
The human role in agentic systems moves earlier: judgement now happens before execution.
What has changed is the proof required: judgement must be shown to hold, not assumed because a human was present.
Founder & Managing Director
Proving the Decision: What Agentic AI Requires of Human Judgement Now
Agentic AI moves the human decision earlier and compresses the time to make it, raising the bar for what counts as judgement rather than reflex. The question now is whether the person still in the loop can see clearly, hold their position under speed and pressure, and exercise authority they can prove. This session sets out what agentic AI requires of human judgement now: decisions tested under time compression, evidenced when they matter, and owned by a named person who can show they held. Humans still decide. The proof required to show that judgement holds is what has changed. Key takeaways:
Judgement counts as authority only when it has been tested under real pressure and time compression.
The human role in agentic systems moves earlier: judgement now happens before execution.
What has changed is the proof required: judgement must be shown to hold, not assumed because a human was present.

AI Lead, UK&I
AI and the battle for creativity
Every industry is asking the same question: what can we do that AI can’t? For the marketing and creative industries, solace has been taken in the belief that the answer lies in the sacred human skill of creativity. But what if AI can in fact be creative? What would that mean for how we use the technology and do marketing in the future? Would this be existential for the future of creative agencies or would this unlock a new approach to marketing?
AI Lead, UK&I
AI and the battle for creativity
Every industry is asking the same question: what can we do that AI can’t? For the marketing and creative industries, solace has been taken in the belief that the answer lies in the sacred human skill of creativity. But what if AI can in fact be creative? What would that mean for how we use the technology and do marketing in the future? Would this be existential for the future of creative agencies or would this unlock a new approach to marketing?
Artist-Founder
AI to Real and Back to AI
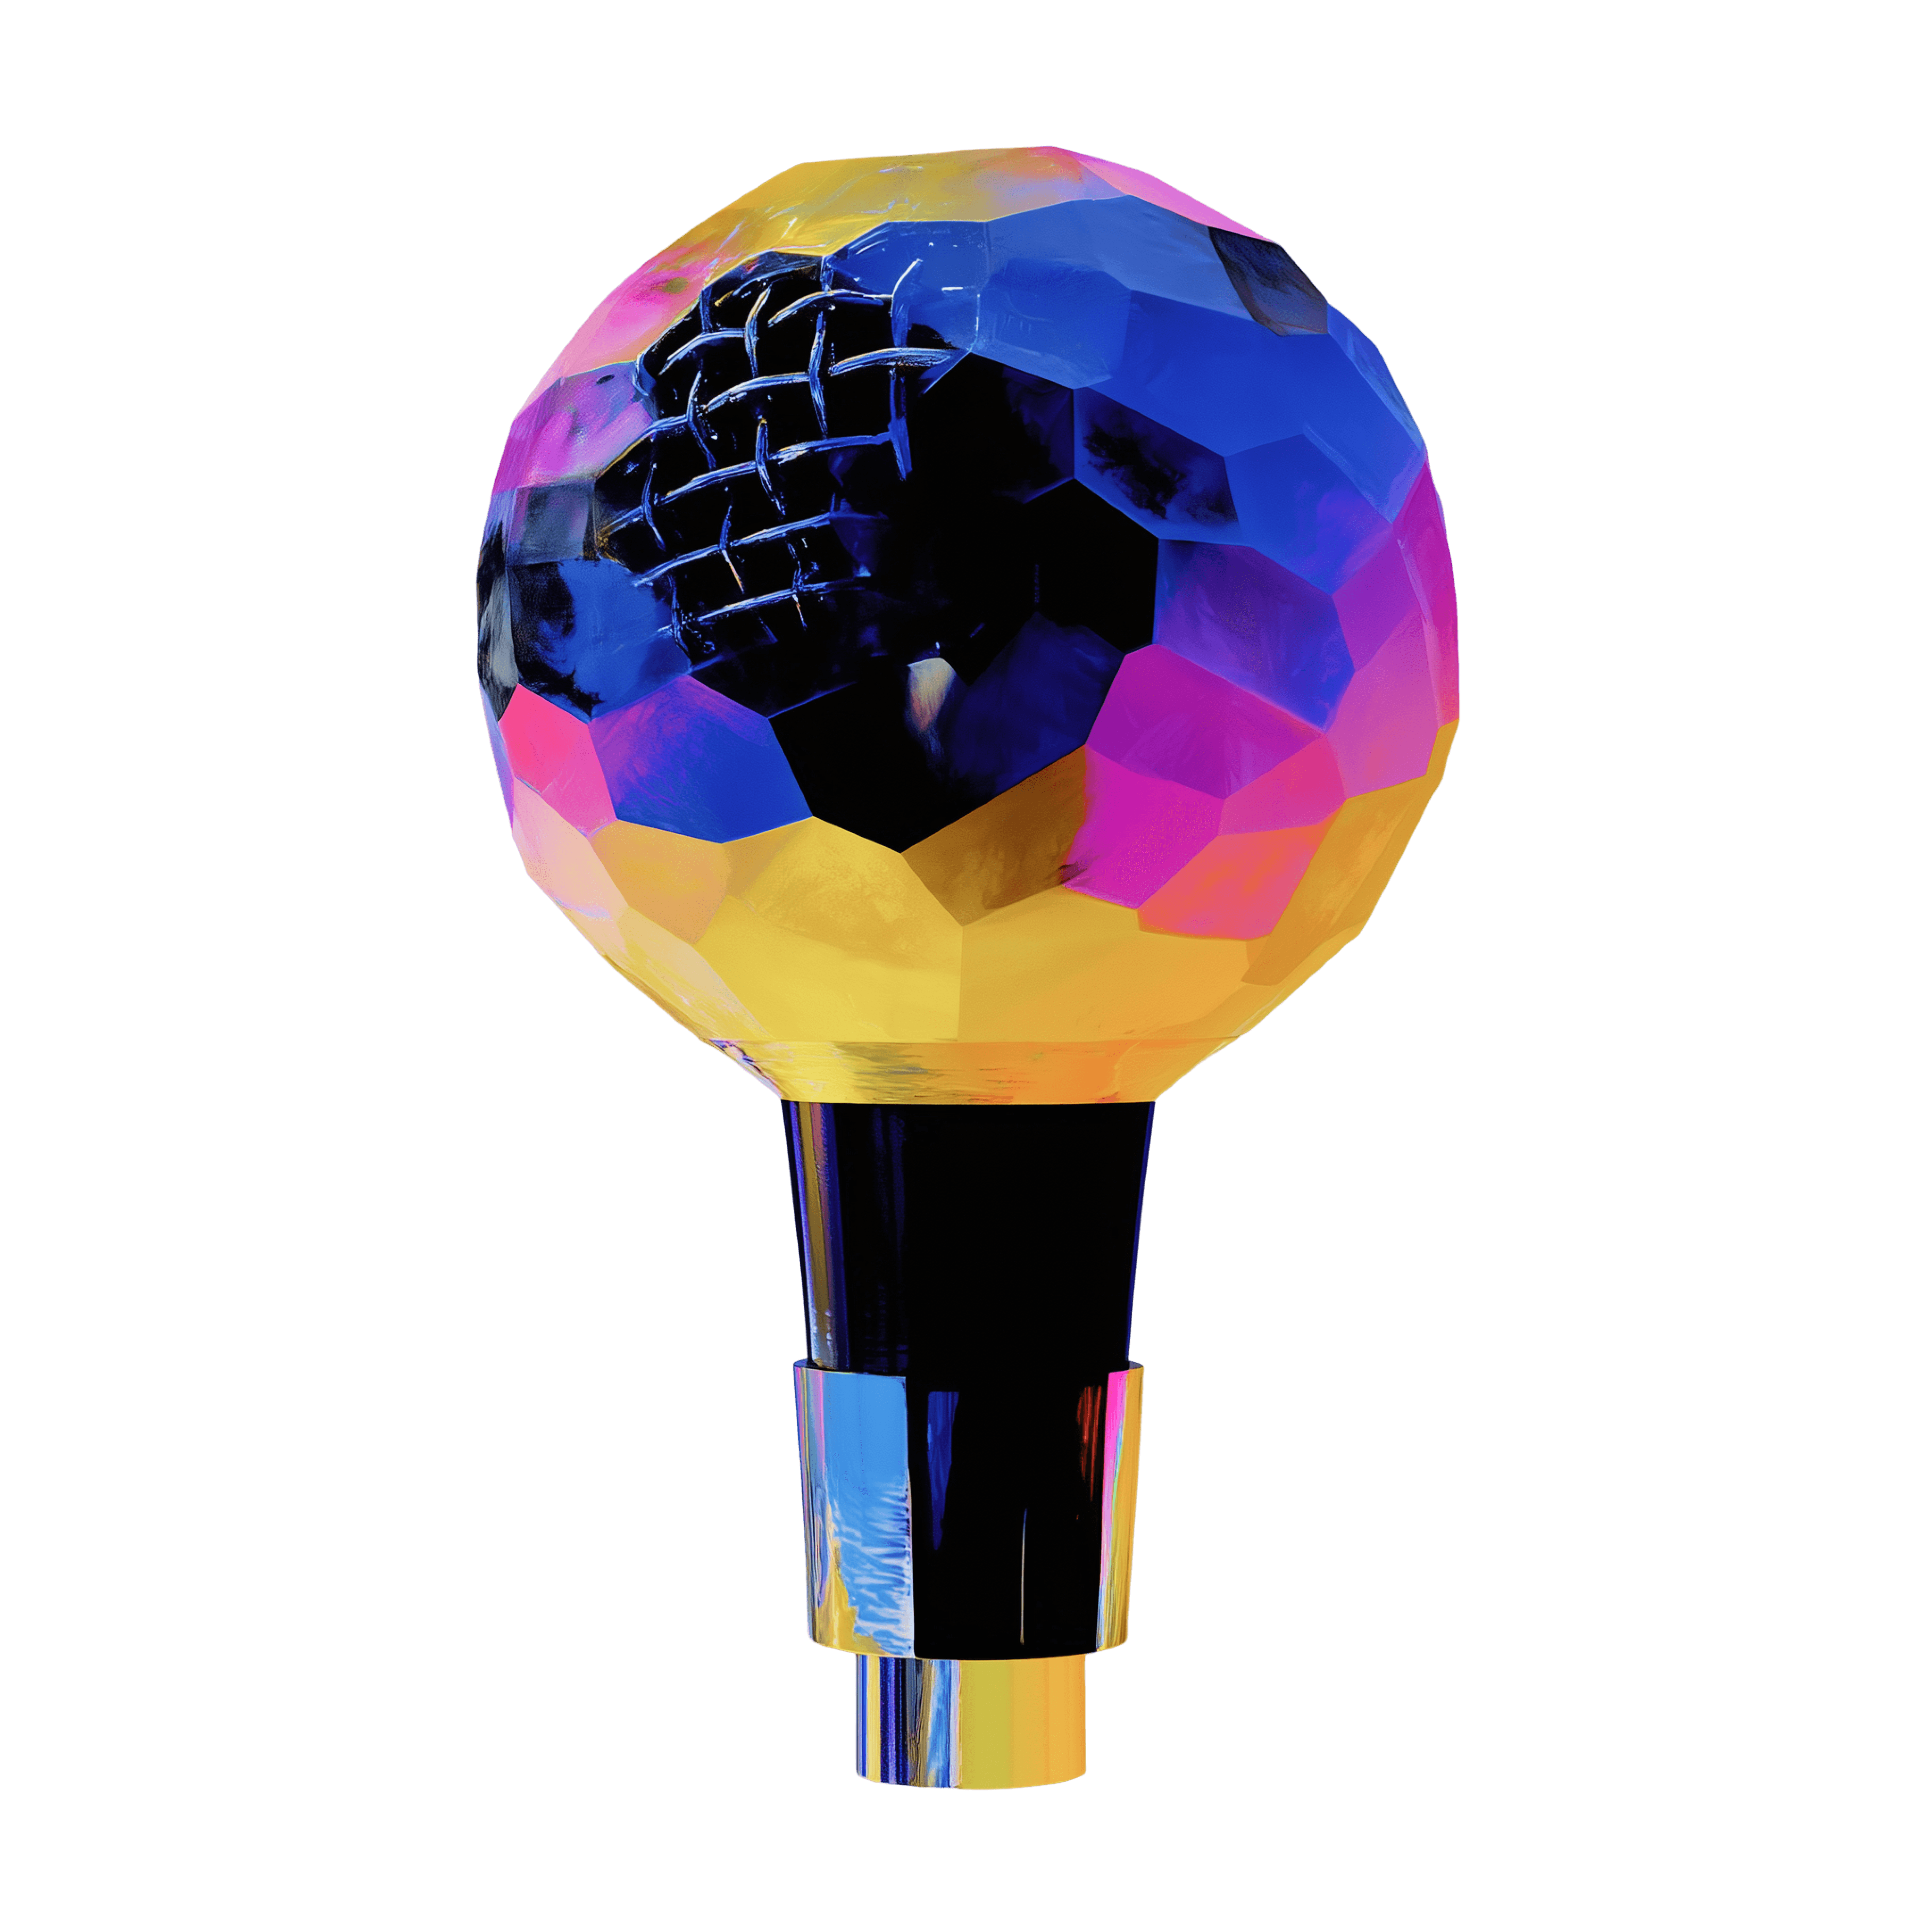
The Neural Forest digital art project introduces a pioneering "phygital" approach that materialises digital concepts into tangible, premium video sculptures. While advanced generative AI tools expand the limits of imagination, their visual art outputs typically remain trapped as fleeting pixels on a screen. This project bridges that virtual-physical divide, transforming fluid digital files into high-value, physical art assets.
The production pipeline seamlessly moves from initial concept to digital fabrication. In a collaboration between human and machine, 3D mesh modelling is used, continuing through industrial 3D printing, and high-gloss chrome plating. And raw organic structures are transformed into reflective chrome-finished sculptures. These physical forms securely cradle LCD screens running custom video loop artworks made from a unique combination of photography, AI, and datamoshing.
Looking ahead, Neural Forest heralds the transition towards a metamorphic engine that bridges digital concepts and tangible reality. It points to a future of pure creation, where machines will materialise ideas into diverse physical forms, ranging from synthetic compounds, and eventually, the human form itself. This presentation demonstrates a sophisticated pipeline where AI and nature converge, offering an exclusive look at the future of high-end, tangible digital art.
Artist-Founder
AI to Real and Back to AI
The Neural Forest digital art project introduces a pioneering "phygital" approach that materialises digital concepts into tangible, premium video sculptures. While advanced generative AI tools expand the limits of imagination, their visual art outputs typically remain trapped as fleeting pixels on a screen. This project bridges that virtual-physical divide, transforming fluid digital files into high-value, physical art assets.
The production pipeline seamlessly moves from initial concept to digital fabrication. In a collaboration between human and machine, 3D mesh modelling is used, continuing through industrial 3D printing, and high-gloss chrome plating. And raw organic structures are transformed into reflective chrome-finished sculptures. These physical forms securely cradle LCD screens running custom video loop artworks made from a unique combination of photography, AI, and datamoshing.
Looking ahead, Neural Forest heralds the transition towards a metamorphic engine that bridges digital concepts and tangible reality. It points to a future of pure creation, where machines will materialise ideas into diverse physical forms, ranging from synthetic compounds, and eventually, the human form itself. This presentation demonstrates a sophisticated pipeline where AI and nature converge, offering an exclusive look at the future of high-end, tangible digital art.

Director, Agentic Strategy & Design
99 problems, and AI solved the wrong one.
AI has made doing things almost free. You can brief a tool, walk away and come back an hour later to a polished answer. The catch is that it might be the answer to the wrong question. In marketing, that means a team heading confidently in the wrong direction, at AI speed. This talk is about the one habit that matters more now than before AI: being sure you know what problem you’re solving before you start building.
Director, Agentic Strategy & Design
99 problems, and AI solved the wrong one.
AI has made doing things almost free. You can brief a tool, walk away and come back an hour later to a polished answer. The catch is that it might be the answer to the wrong question. In marketing, that means a team heading confidently in the wrong direction, at AI speed. This talk is about the one habit that matters more now than before AI: being sure you know what problem you’re solving before you start building.

GenAI Tech Lead
Ask, Don't Judge: Decomposing LLM Evaluation into Questions Agents Can Answer
LLM-as-a-judge is everywhere, but a single judge returning a single score is fragile: it can flip when answers are reordered, it rewards length, and it never says what is wrong. This talk argues for a different design: ask, don't judge. Decompose each evaluation into small yes/no questions derived from the task and the source; answer each with the cheapest reliable tool, a rule, an entailment model, or an LLM only where judgment is needed; and let a panel of collaborating agents plan, check and aggregate, escalating where they disagree. In a live demo on public data, we compare a single judge with the panel on agreement with human labels, run-to-run stability and cost, and close with where the approach breaks and how to guard against it.
GenAI Tech Lead
Ask, Don't Judge: Decomposing LLM Evaluation into Questions Agents Can Answer
LLM-as-a-judge is everywhere, but a single judge returning a single score is fragile: it can flip when answers are reordered, it rewards length, and it never says what is wrong. This talk argues for a different design: ask, don't judge. Decompose each evaluation into small yes/no questions derived from the task and the source; answer each with the cheapest reliable tool, a rule, an entailment model, or an LLM only where judgment is needed; and let a panel of collaborating agents plan, check and aggregate, escalating where they disagree. In a live demo on public data, we compare a single judge with the panel on agreement with human labels, run-to-run stability and cost, and close with where the approach breaks and how to guard against it.

CEO
Brand craft, not slop: turning AI generation into usable business content
Generative AI can produce a video or voiceover in seconds. Producing content your brand can actually use is a different job. Ask AI for the same thing twice and you’ll get two different results: a new read of the script, a new pronunciation of your product name, a different look for your product. That’s slop.
Fraser Bell, CEO of Wondercraft, breaks down what it takes to go from AI generation to consistent, brand-ready video and audio. He’ll cover the craft decisions that make the difference, from voice selection and custom pronunciations to editing control, and where AI should do the work versus where a person should.
He’ll also explain why finishing a piece takes more than one model, and the legal questions brands should ask before publishing AI content.
Key takeaways:
Practical advice for making AI audio and video brand-ready
Which steps to automate and which still need human judgement
How to set up tools and workflow so a team can finish the job
The legal protections to have in place before AI content goes out
Can Europe Lead the Future of GenAI?
CEO
Brand craft, not slop: turning AI generation into usable business content
Generative AI can produce a video or voiceover in seconds. Producing content your brand can actually use is a different job. Ask AI for the same thing twice and you’ll get two different results: a new read of the script, a new pronunciation of your product name, a different look for your product. That’s slop.
Fraser Bell, CEO of Wondercraft, breaks down what it takes to go from AI generation to consistent, brand-ready video and audio. He’ll cover the craft decisions that make the difference, from voice selection and custom pronunciations to editing control, and where AI should do the work versus where a person should.
He’ll also explain why finishing a piece takes more than one model, and the legal questions brands should ask before publishing AI content.
Key takeaways:
Practical advice for making AI audio and video brand-ready
Which steps to automate and which still need human judgement
How to set up tools and workflow so a team can finish the job
The legal protections to have in place before AI content goes out
Can Europe Lead the Future of GenAI?

Senior Software Engineer
AI Is Only as Good as Its Context: How Organizations Can Become AI-Native
Most organizations already have AI tools, but few work in an AI-native way. In this talk I'll go through what I think it takes to get there. It starts with people. They have to give up ways of working they're comfortable with. Power users need room to build tools and show others how it's done. And every few months we need to check again what AI can reliably do. I think the real bottleneck, though, is organizational context. An agent can only see the context we give it. Most of what an org knows is never written down, is stuck in silos, or loses the framing that gives it meaning. I'll cover why this is hard and what the solution is starting to look like.
From GenAI Tools to GenAI-Native Organisations
Senior Software Engineer
AI Is Only as Good as Its Context: How Organizations Can Become AI-Native
Most organizations already have AI tools, but few work in an AI-native way. In this talk I'll go through what I think it takes to get there. It starts with people. They have to give up ways of working they're comfortable with. Power users need room to build tools and show others how it's done. And every few months we need to check again what AI can reliably do. I think the real bottleneck, though, is organizational context. An agent can only see the context we give it. Most of what an org knows is never written down, is stuck in silos, or loses the framing that gives it meaning. I'll cover why this is hard and what the solution is starting to look like.
From GenAI Tools to GenAI-Native Organisations

Marketing Transformation: People, platforms and perseverance.
Mark Dewings (CEO, Ogilvy Consulting UK) will host Kate Mackie (Chief Marketing Strategy & Operations Officer, EY), Özgür Kirazci (Senior Marketing Director, EMEA Platforms and Devices, Google) and Dr Laura Weiss (WPP, Human-AI Strategy & Workforce Planning Lead) to hear their views on AI-enabled marketing transformation. The discussion will cover what has actually changed, how organisations should transform, views on the future marketing organisation, and more.
Marketing Transformation: People, platforms and perseverance.
Mark Dewings (CEO, Ogilvy Consulting UK) will host Kate Mackie (Chief Marketing Strategy & Operations Officer, EY), Özgür Kirazci (Senior Marketing Director, EMEA Platforms and Devices, Google) and Dr Laura Weiss (WPP, Human-AI Strategy & Workforce Planning Lead) to hear their views on AI-enabled marketing transformation. The discussion will cover what has actually changed, how organisations should transform, views on the future marketing organisation, and more.

Founder
Who Is Your AI Agent? Identity, Trust and Accountability in the Agentic Web
Soon, billions of AI agents may negotiate, buy, sell, hire, code, advise and transact on behalf of people and companies. But before agents can become economic actors, we need to solve a foundational problem: identity.
How will one agent know whether another is legitimate? Who authorised it? What reputation does it carry? What can it access, delegate or commit to?
This talk introduces Know Your Agent (KYA) - a trust and identity layer for the emerging machine economy. It explores how identity, credentials, permissions, provenance and reputation could enable autonomous agents to safely interact with humans, organisations and each other.
The future of AI may not be about knowing your customer. It may be about knowing their agent.
Founder
Who Is Your AI Agent? Identity, Trust and Accountability in the Agentic Web
Soon, billions of AI agents may negotiate, buy, sell, hire, code, advise and transact on behalf of people and companies. But before agents can become economic actors, we need to solve a foundational problem: identity.
How will one agent know whether another is legitimate? Who authorised it? What reputation does it carry? What can it access, delegate or commit to?
This talk introduces Know Your Agent (KYA) - a trust and identity layer for the emerging machine economy. It explores how identity, credentials, permissions, provenance and reputation could enable autonomous agents to safely interact with humans, organisations and each other.
The future of AI may not be about knowing your customer. It may be about knowing their agent.

Co-Founder & CTO
The Art of Evals: Building a Benchmark From Zero
How do you evaluate an AI system when no suitable benchmark exists and the data you need is difficult to obtain?
This talk follows the construction of a semi-synthetic benchmark for detecting errors in US medical bills. Starting with public healthcare data, we reconstructed clinical encounters, incorporated hospital pricing, and introduced controlled billing errors. Each step required decisions about realism, coverage, and what “good performance” should mean.
Metric design proved just as important as the dataset; catching ten small billing errors while missing one expensive error can reward a model without helping the patient. We designed metrics to better capture patient financial utility, examined performance across models, and identified limitations that still require expert validation.
Takeaways:
Build evaluation data through grounded synthesis, when real examples are not available.
Assess benchmarks for coverage, alignment, realism, and room for improvement.
Choose metrics that reflect user outcomes, including the consequences of false positives.
Recognize the pros and cons of synthetic eval data.
Co-Founder & CTO
The Art of Evals: Building a Benchmark From Zero
How do you evaluate an AI system when no suitable benchmark exists and the data you need is difficult to obtain?
This talk follows the construction of a semi-synthetic benchmark for detecting errors in US medical bills. Starting with public healthcare data, we reconstructed clinical encounters, incorporated hospital pricing, and introduced controlled billing errors. Each step required decisions about realism, coverage, and what “good performance” should mean.
Metric design proved just as important as the dataset; catching ten small billing errors while missing one expensive error can reward a model without helping the patient. We designed metrics to better capture patient financial utility, examined performance across models, and identified limitations that still require expert validation.
Takeaways:
Build evaluation data through grounded synthesis, when real examples are not available.
Assess benchmarks for coverage, alignment, realism, and room for improvement.
Choose metrics that reflect user outcomes, including the consequences of false positives.
Recognize the pros and cons of synthetic eval data.

Senior Leader and Advisor
Engineering Leaders Must Build Again: Why, and How to Start
Agentic AI is changing the fundamentals of engineering, and engineering leaders who haven’t stayed close enough to the craft run the risk of leading their teams through a change they don’t fully understand. Spending some time building again is the best way to get exposure to this new, evolving engineering practice, and so be a better leader for your team. But that can feel like a daunting task.
This talk is about how I got back to building and experimenting with agentic flows after years away from hands-on work. I’ll share the blueprint I followed, and the specific tools and resources I used along the way.
You’ll leave with a clear reason to start, and a way to do it starting tomorrow.
Senior Leader and Advisor
Engineering Leaders Must Build Again: Why, and How to Start
Agentic AI is changing the fundamentals of engineering, and engineering leaders who haven’t stayed close enough to the craft run the risk of leading their teams through a change they don’t fully understand. Spending some time building again is the best way to get exposure to this new, evolving engineering practice, and so be a better leader for your team. But that can feel like a daunting task.
This talk is about how I got back to building and experimenting with agentic flows after years away from hands-on work. I’ll share the blueprint I followed, and the specific tools and resources I used along the way.
You’ll leave with a clear reason to start, and a way to do it starting tomorrow.

C-Founder & Growth Advisor
From Brief to Times Square in 68 Days: How etoro x Curious Endeavor Rebuilt Its Brand with AI
etoro, a global investing platform with 40 million registered users in 75 countries, was launching AI-powered trading in 2026. It wanted a new brand made the same way: with AI, at the speed of every market, without losing creative quality.
The problem: AI tools make content fast, but most of it looks generic, breaks brand rules or misses compliance lines. A studio working by hand cannot keep up with every size, market and language.
Our approach: Curious Endeavor built the CE exoskeleton, a creative system that holds the brand's rules and taste and works inside the tools the team already uses, including Figma. It turns a short brief into on-brand banners, builds web pages from the brand's own components, and checks every piece before it goes out. People keep the judgment; the system does the volume.
The result: the new brand launched on 7 July 2026, from London to Times Square, 68 days after work began, with 697 pieces of work on record. Web designers now build 30 pages a day instead of 2, and junior designers run full campaigns from day one.
Key takeaways: AI pays off when it is built around a brand and its team. Craft and compliance can scale together. The same pattern works for any brand with many markets and little time.
C-Founder & Growth Advisor
From Brief to Times Square in 68 Days: How etoro x Curious Endeavor Rebuilt Its Brand with AI
etoro, a global investing platform with 40 million registered users in 75 countries, was launching AI-powered trading in 2026. It wanted a new brand made the same way: with AI, at the speed of every market, without losing creative quality.
The problem: AI tools make content fast, but most of it looks generic, breaks brand rules or misses compliance lines. A studio working by hand cannot keep up with every size, market and language.
Our approach: Curious Endeavor built the CE exoskeleton, a creative system that holds the brand's rules and taste and works inside the tools the team already uses, including Figma. It turns a short brief into on-brand banners, builds web pages from the brand's own components, and checks every piece before it goes out. People keep the judgment; the system does the volume.
The result: the new brand launched on 7 July 2026, from London to Times Square, 68 days after work began, with 697 pieces of work on record. Web designers now build 30 pages a day instead of 2, and junior designers run full campaigns from day one.
Key takeaways: AI pays off when it is built around a brand and its team. Craft and compliance can scale together. The same pattern works for any brand with many markets and little time.

Founder & CEO
Build the Right Product: AI Product Design Meets Human Insight
AI can now build software in minutes. But building faster doesn't mean building the right product.
As the barriers to software development disappear, the real challenge is shifting from how to build to what is worth building. Founders and designers need more than AI-generated screens. They need better decisions, meaningful experiences, and a connected way to turn ideas into real products.
Fleck AI is an AI-powered, human-guided product design agent built around one mission: helping people build the right product.
Through three connected pathways; Create, Improve, and Showcase, Fleck brings the product design journey into one intelligent workspace.
Create helps users validate ideas, research markets, define requirements, design multi-screen experiences, and prepare developer-ready handoffs.
Improve evaluates existing products through AI-powered UX audits, identifying usability, accessibility, and design issues with actionable recommendations.
Showcase transforms completed work into professional case studies and portfolios, helping designers communicate their decisions and demonstrate their impact.
Powered by persistent Design Memory and personalised Design Taste, Fleck connects context, human insight, and AI across the design process.
With over 3,500 registered users, Fleck demonstrates a different direction for generative AI: not simply producing more interfaces, but helping people create better products, improve experiences, and showcase meaningful work.
Founder & CEO
Build the Right Product: AI Product Design Meets Human Insight
AI can now build software in minutes. But building faster doesn't mean building the right product.
As the barriers to software development disappear, the real challenge is shifting from how to build to what is worth building. Founders and designers need more than AI-generated screens. They need better decisions, meaningful experiences, and a connected way to turn ideas into real products.
Fleck AI is an AI-powered, human-guided product design agent built around one mission: helping people build the right product.
Through three connected pathways; Create, Improve, and Showcase, Fleck brings the product design journey into one intelligent workspace.
Create helps users validate ideas, research markets, define requirements, design multi-screen experiences, and prepare developer-ready handoffs.
Improve evaluates existing products through AI-powered UX audits, identifying usability, accessibility, and design issues with actionable recommendations.
Showcase transforms completed work into professional case studies and portfolios, helping designers communicate their decisions and demonstrate their impact.
Powered by persistent Design Memory and personalised Design Taste, Fleck connects context, human insight, and AI across the design process.
With over 3,500 registered users, Fleck demonstrates a different direction for generative AI: not simply producing more interfaces, but helping people create better products, improve experiences, and showcase meaningful work.

Founder
What If AI Agents Could Time Travel?
What if AI agents could live slightly ahead of us in time?
For decades, technology has helped us understand the past and navigate the present. But what if the next generation of personal AI could help us shape what happens next?
Today's AI assistants are becoming increasingly capable, yet most interactions still begin with a request. We ask, they respond. Finalit is exploring a different relationship between people and intelligence: one where an AI agent anticipates what matters and helps us act while there's still time to make a difference.
Finalit is a personal AI agent that lives in your messages, designed to look ahead, anticipate everyday needs and help you stay one step ahead of what's coming.
This talk introduces the vision behind Finalit and explores what becomes possible when personal AI moves beyond responding to the present and starts preparing us for the future.
Founder
What If AI Agents Could Time Travel?
What if AI agents could live slightly ahead of us in time?
For decades, technology has helped us understand the past and navigate the present. But what if the next generation of personal AI could help us shape what happens next?
Today's AI assistants are becoming increasingly capable, yet most interactions still begin with a request. We ask, they respond. Finalit is exploring a different relationship between people and intelligence: one where an AI agent anticipates what matters and helps us act while there's still time to make a difference.
Finalit is a personal AI agent that lives in your messages, designed to look ahead, anticipate everyday needs and help you stay one step ahead of what's coming.
This talk introduces the vision behind Finalit and explores what becomes possible when personal AI moves beyond responding to the present and starts preparing us for the future.

Founder
Can you stop it in time? Intervention readiness for AI in finance
When an automated decision goes wrong, a customer lives with the result: a payment wrongly blocked, a loan wrongly declined, a fault that grows while each team waits for someone more senior to act. AI makes these failures faster. Most firms can name the executive accountable for their AI systems. Far fewer can show that this person would be reached, would decide and would act before the harm became irreversible.
This talk introduces intervention readiness: the ability to detect a failing system, escalate it to someone with authority, decide, and intervene in time. It presents AGDA®, Intervene's assessment of one named system against four stages in order, timed against that system's own harm window. Each assessment ends in one evidenced verdict: before impact, at risk or after impact.
Using a constructed retail credit example, the talk shows where the chain breaks and why, in that example, faster detection would not fix it.
Three takeaways for leaders deploying AI:
Governance is an input. Intervention capability is the outcome.
The weakest stage sets the result, so test the whole chain.
Start with one consequential system and ask: can we stop it in time?
Founder
Can you stop it in time? Intervention readiness for AI in finance
When an automated decision goes wrong, a customer lives with the result: a payment wrongly blocked, a loan wrongly declined, a fault that grows while each team waits for someone more senior to act. AI makes these failures faster. Most firms can name the executive accountable for their AI systems. Far fewer can show that this person would be reached, would decide and would act before the harm became irreversible.
This talk introduces intervention readiness: the ability to detect a failing system, escalate it to someone with authority, decide, and intervene in time. It presents AGDA®, Intervene's assessment of one named system against four stages in order, timed against that system's own harm window. Each assessment ends in one evidenced verdict: before impact, at risk or after impact.
Using a constructed retail credit example, the talk shows where the chain breaks and why, in that example, faster detection would not fix it.
Three takeaways for leaders deploying AI:
Governance is an input. Intervention capability is the outcome.
The weakest stage sets the result, so test the whole chain.
Start with one consequential system and ask: can we stop it in time?

Co-founder
Opening Remarks
Eric Anderegg, Co-founder of GenAI London, GenAI Zürich and GenAI Berlin, opens the GenAI London 2026 conference at the Queen Elizabeth II Centre, just steps from Big Ben, the Houses of Parliament and Westminster Abbey. His opening remarks set the stage for a day exploring how organisations are putting GenAI into practice.
Can Europe Lead the Future of GenAI?
Closing Remarks
The closing ceremony of GenAI London 2026.
Co-founder
Opening Remarks
Eric Anderegg, Co-founder of GenAI London, GenAI Zürich and GenAI Berlin, opens the GenAI London 2026 conference at the Queen Elizabeth II Centre, just steps from Big Ben, the Houses of Parliament and Westminster Abbey. His opening remarks set the stage for a day exploring how organisations are putting GenAI into practice.
Can Europe Lead the Future of GenAI?
Closing Remarks
The closing ceremony of GenAI London 2026.

Co-Founder
From GenAI Tools to GenAI-Native Organisations
Closing Remarks
The closing ceremony of GenAI London 2026.
Co-Founder
From GenAI Tools to GenAI-Native Organisations
Closing Remarks
The closing ceremony of GenAI London 2026.

Director
Thousands of Controls, One Risk Picture: GenAI in Risk & Compliance
Risk and compliance teams in financial services manage large control environments against a growing body of regulation. Mapping those controls to internal standards and external requirements takes significant specialist effort, and senior leaders still struggle to see the organisation's overall risk position and where mitigation matters most.
This talk shows how an AI-enabled Risk & Compliance transformation at a systemically critical financial market infrastructure provider tackled both problems. Redesigned governance, reporting and processes were combined with GenAI that maps several thousand controls to internal standards and hundreds of regulatory requirements, feeding executive dashboards for risk oversight.
Specialists stayed in the loop and kept responsibility for quality and accountability. The result: around 80% less effort for risk and compliance managers – hundreds of staff-days a year, including senior management time – and a repeatable approach to applying GenAI in a highly regulated environment.
Key takeaways:
→ In regulated industries, GenAI works best as an accelerator inside redesigned governance, not as a bolt-on.
→ A human-in-the-loop model keeps experts accountable while freeing them for judgement.
→ Give leaders one clear view of risk and mitigation priorities, and the effort savings follow.
Director
Thousands of Controls, One Risk Picture: GenAI in Risk & Compliance
Risk and compliance teams in financial services manage large control environments against a growing body of regulation. Mapping those controls to internal standards and external requirements takes significant specialist effort, and senior leaders still struggle to see the organisation's overall risk position and where mitigation matters most.
This talk shows how an AI-enabled Risk & Compliance transformation at a systemically critical financial market infrastructure provider tackled both problems. Redesigned governance, reporting and processes were combined with GenAI that maps several thousand controls to internal standards and hundreds of regulatory requirements, feeding executive dashboards for risk oversight.
Specialists stayed in the loop and kept responsibility for quality and accountability. The result: around 80% less effort for risk and compliance managers – hundreds of staff-days a year, including senior management time – and a repeatable approach to applying GenAI in a highly regulated environment.
Key takeaways:
→ In regulated industries, GenAI works best as an accelerator inside redesigned governance, not as a bolt-on.
→ A human-in-the-loop model keeps experts accountable while freeing them for judgement.
→ Give leaders one clear view of risk and mitigation priorities, and the effort savings follow.

MellyGuard: GenAI for Financial Crime Operations, from Onboarding to Oversight
Financial institutions face rising digital fraud, siloed data and slow manual investigations that drain compliance teams and expose digital channels to financial and reputational risk.
MellyGuard, built by Datamellon, is a GenAI-powered platform that brings real-time fraud detection, AML and sanctions screening and automated case management into one financial crime operations workflow: corporate onboarding, beneficial ownership verification, director screening, risk assessment, investigation, MLRO oversight and regulatory reporting.
This session walks through that end-to-end workflow and how it was validated across 11 operational personas – from KYC onboarding and fraud operations to internal audit and executive management – ahead of its pilot launch.
Key takeaways:
→ Why financial crime tools fall short when onboarding, screening and investigation live in separate silos.
→ Where GenAI can cut false positives and speed up risk decisions, and where people stay in charge.
→ What it takes to get a regulated platform ready for subject-matter-expert review.
MellyGuard: GenAI for Financial Crime Operations, from Onboarding to Oversight
Financial institutions face rising digital fraud, siloed data and slow manual investigations that drain compliance teams and expose digital channels to financial and reputational risk.
MellyGuard, built by Datamellon, is a GenAI-powered platform that brings real-time fraud detection, AML and sanctions screening and automated case management into one financial crime operations workflow: corporate onboarding, beneficial ownership verification, director screening, risk assessment, investigation, MLRO oversight and regulatory reporting.
This session walks through that end-to-end workflow and how it was validated across 11 operational personas – from KYC onboarding and fraud operations to internal audit and executive management – ahead of its pilot launch.
Key takeaways:
→ Why financial crime tools fall short when onboarding, screening and investigation live in separate silos.
→ Where GenAI can cut false positives and speed up risk decisions, and where people stay in charge.
→ What it takes to get a regulated platform ready for subject-matter-expert review.

Business Development Director, UK & Ireland
MellyGuard: GenAI for Financial Crime Operations, from Onboarding to Oversight
Financial institutions face rising digital fraud, siloed data and slow manual investigations that drain compliance teams and expose digital channels to financial and reputational risk.
MellyGuard, built by Datamellon, is a GenAI-powered platform that brings real-time fraud detection, AML and sanctions screening and automated case management into one financial crime operations workflow: corporate onboarding, beneficial ownership verification, director screening, risk assessment, investigation, MLRO oversight and regulatory reporting.
This session walks through that end-to-end workflow and how it was validated across 11 operational personas – from KYC onboarding and fraud operations to internal audit and executive management – ahead of its pilot launch.
Key takeaways:
→ Why financial crime tools fall short when onboarding, screening and investigation live in separate silos.
→ Where GenAI can cut false positives and speed up risk decisions, and where people stay in charge.
→ What it takes to get a regulated platform ready for subject-matter-expert review.
Business Development Director, UK & Ireland
MellyGuard: GenAI for Financial Crime Operations, from Onboarding to Oversight
Financial institutions face rising digital fraud, siloed data and slow manual investigations that drain compliance teams and expose digital channels to financial and reputational risk.
MellyGuard, built by Datamellon, is a GenAI-powered platform that brings real-time fraud detection, AML and sanctions screening and automated case management into one financial crime operations workflow: corporate onboarding, beneficial ownership verification, director screening, risk assessment, investigation, MLRO oversight and regulatory reporting.
This session walks through that end-to-end workflow and how it was validated across 11 operational personas – from KYC onboarding and fraud operations to internal audit and executive management – ahead of its pilot launch.
Key takeaways:
→ Why financial crime tools fall short when onboarding, screening and investigation live in separate silos.
→ Where GenAI can cut false positives and speed up risk decisions, and where people stay in charge.
→ What it takes to get a regulated platform ready for subject-matter-expert review.

MellyGuard: GenAI for Financial Crime Operations, from Onboarding to Oversight
Financial institutions face rising digital fraud, siloed data and slow manual investigations that drain compliance teams and expose digital channels to financial and reputational risk.
MellyGuard, built by Datamellon, is a GenAI-powered platform that brings real-time fraud detection, AML and sanctions screening and automated case management into one financial crime operations workflow: corporate onboarding, beneficial ownership verification, director screening, risk assessment, investigation, MLRO oversight and regulatory reporting.
This session walks through that end-to-end workflow and how it was validated across 11 operational personas – from KYC onboarding and fraud operations to internal audit and executive management – ahead of its pilot launch.
Key takeaways:
→ Why financial crime tools fall short when onboarding, screening and investigation live in separate silos.
→ Where GenAI can cut false positives and speed up risk decisions, and where people stay in charge.
→ What it takes to get a regulated platform ready for subject-matter-expert review.
MellyGuard: GenAI for Financial Crime Operations, from Onboarding to Oversight
Financial institutions face rising digital fraud, siloed data and slow manual investigations that drain compliance teams and expose digital channels to financial and reputational risk.
MellyGuard, built by Datamellon, is a GenAI-powered platform that brings real-time fraud detection, AML and sanctions screening and automated case management into one financial crime operations workflow: corporate onboarding, beneficial ownership verification, director screening, risk assessment, investigation, MLRO oversight and regulatory reporting.
This session walks through that end-to-end workflow and how it was validated across 11 operational personas – from KYC onboarding and fraud operations to internal audit and executive management – ahead of its pilot launch.
Key takeaways:
→ Why financial crime tools fall short when onboarding, screening and investigation live in separate silos.
→ Where GenAI can cut false positives and speed up risk decisions, and where people stay in charge.
→ What it takes to get a regulated platform ready for subject-matter-expert review.

More speakers will be announced shortly
More speakers will be announced shortly
Sponsors and partners
Supported by forward-thinking companies shaping the GenAI transformation
Our esteemed partners are pushing the boundaries of what's possible with Generative AI. Be part of the GenAI leaders shaping what’s next.
GenAI Masters


GenAI Next

Special Partner for Ethical AI, Cybersecurity Governance & Human Rights


Sponsors and partners
Supported by forward-thinking companies shaping the GenAI transformation
Our esteemed partners are pushing the boundaries of what's possible with Generative AI. Be part of the GenAI leaders shaping what’s next.
GenAI Masters
GenAI Next
Special Partner for Ethical AI, Cybersecurity Governance & Human Rights
Join us
Europe’s go-to conference for GenAI leaders and enthusiasts
Attend GenAI London to stay at the forefront of Generative AI, connect with the minds shaping the technology’s future, and explore its real-world impact across industries.

Join us
Europe’s go-to conference for GenAI leaders and enthusiasts
Attend GenAI London to stay at the forefront of Generative AI, connect with the minds shaping the technology’s future, and explore its real-world impact across industries.
Join us
Europe’s go-to conference for GenAI leaders and enthusiasts
Attend GenAI London to stay at the forefront of Generative AI, connect with the minds shaping the technology’s future, and explore its real-world impact across industries.